Center for Data Science and Artificial Intelligence
From Data to Discovery
Unlocking the Power of Biomedical Information
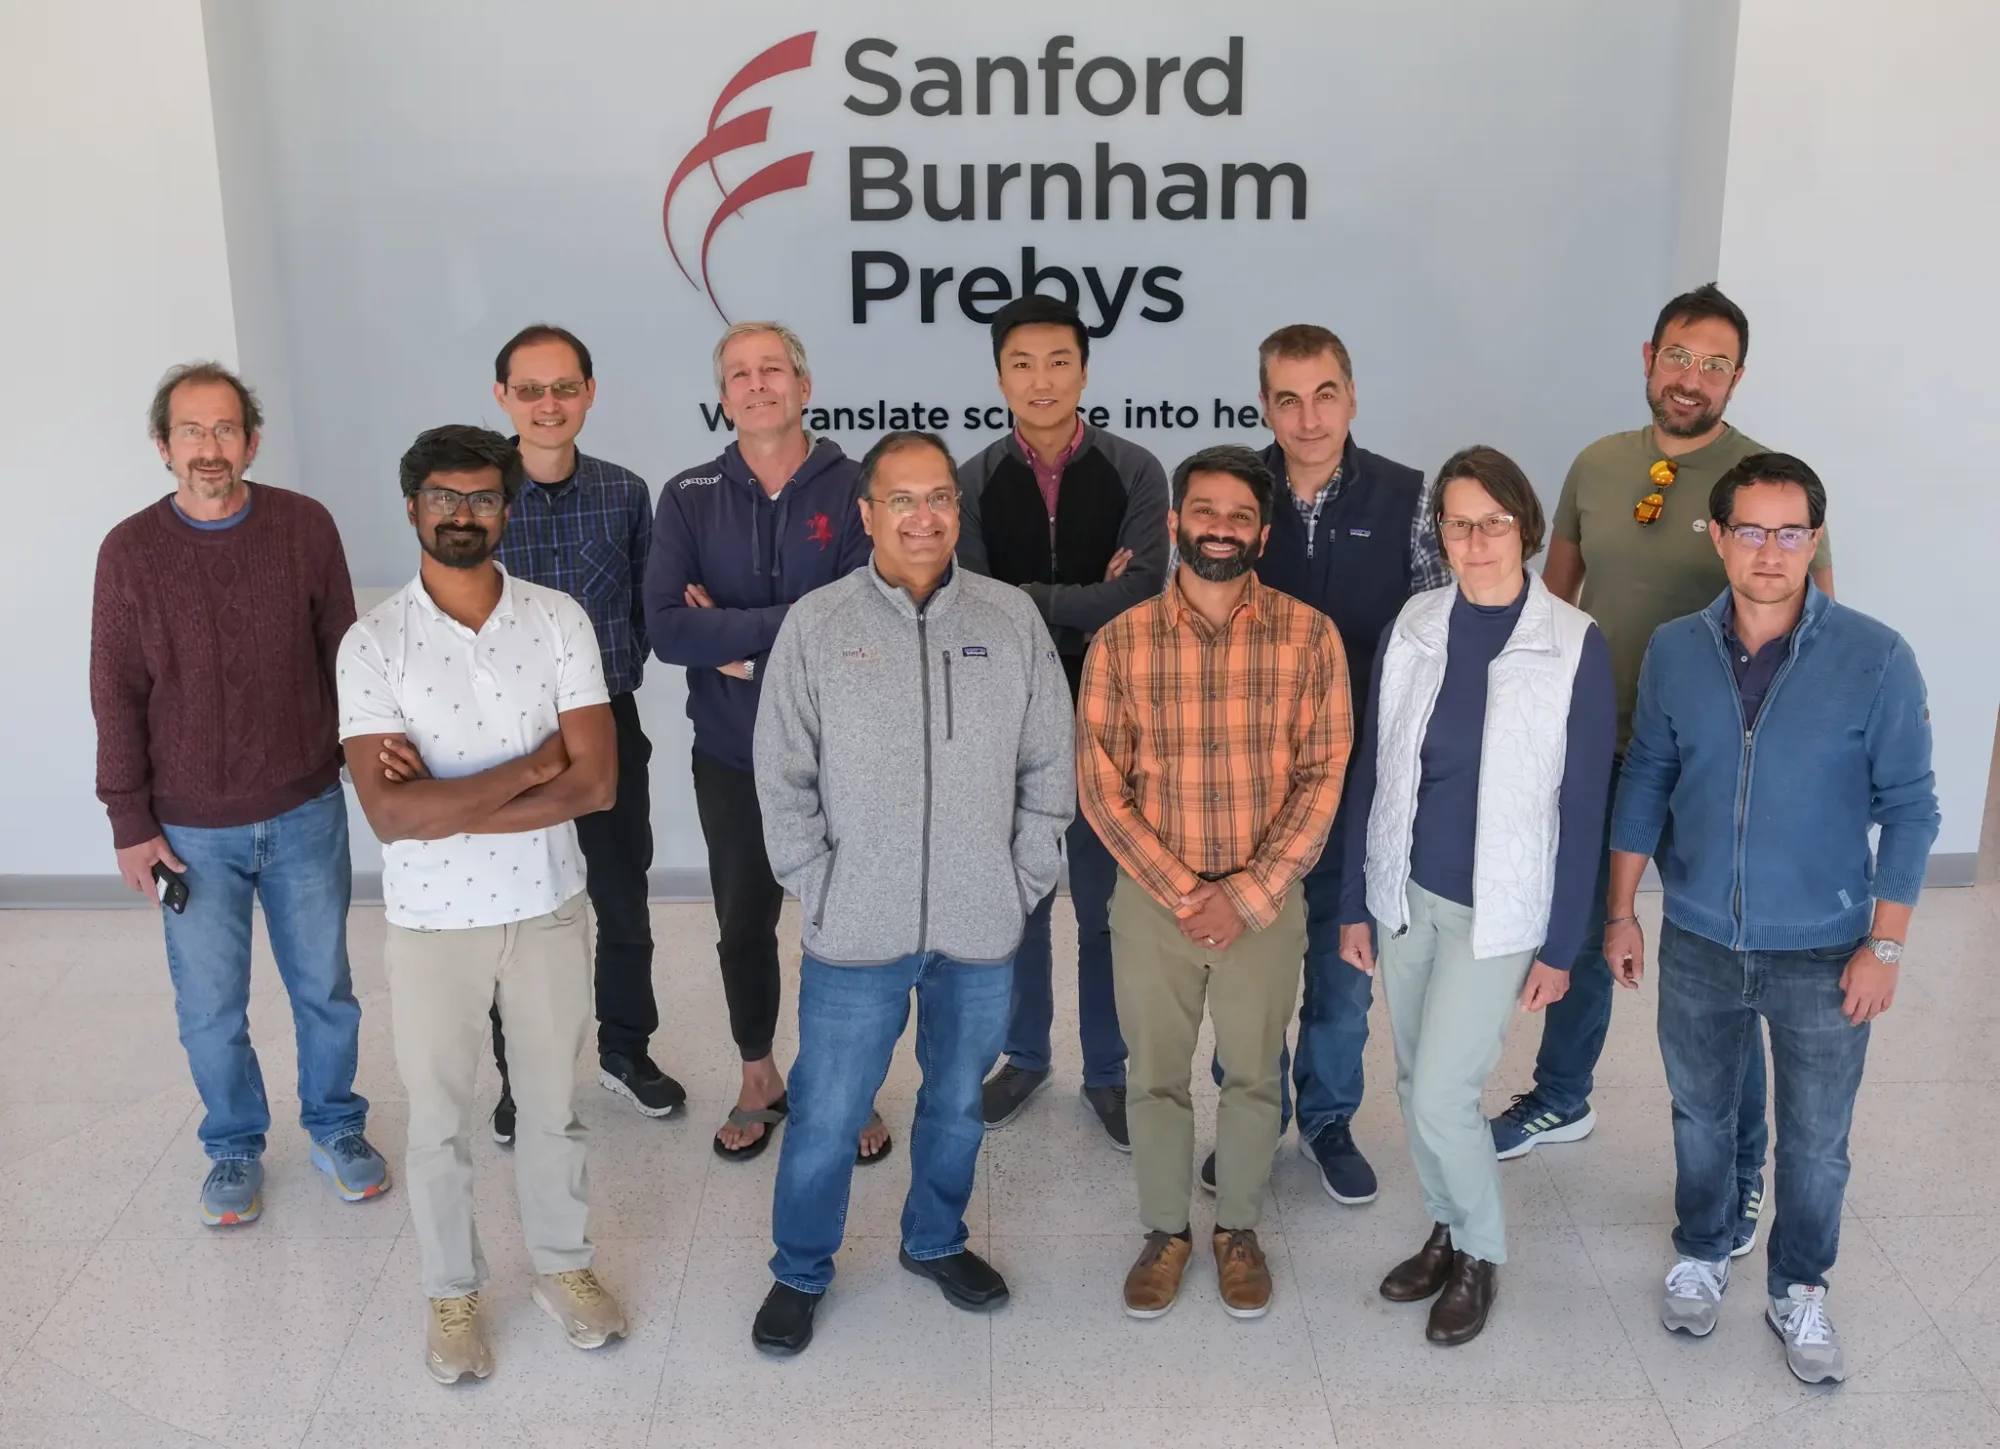
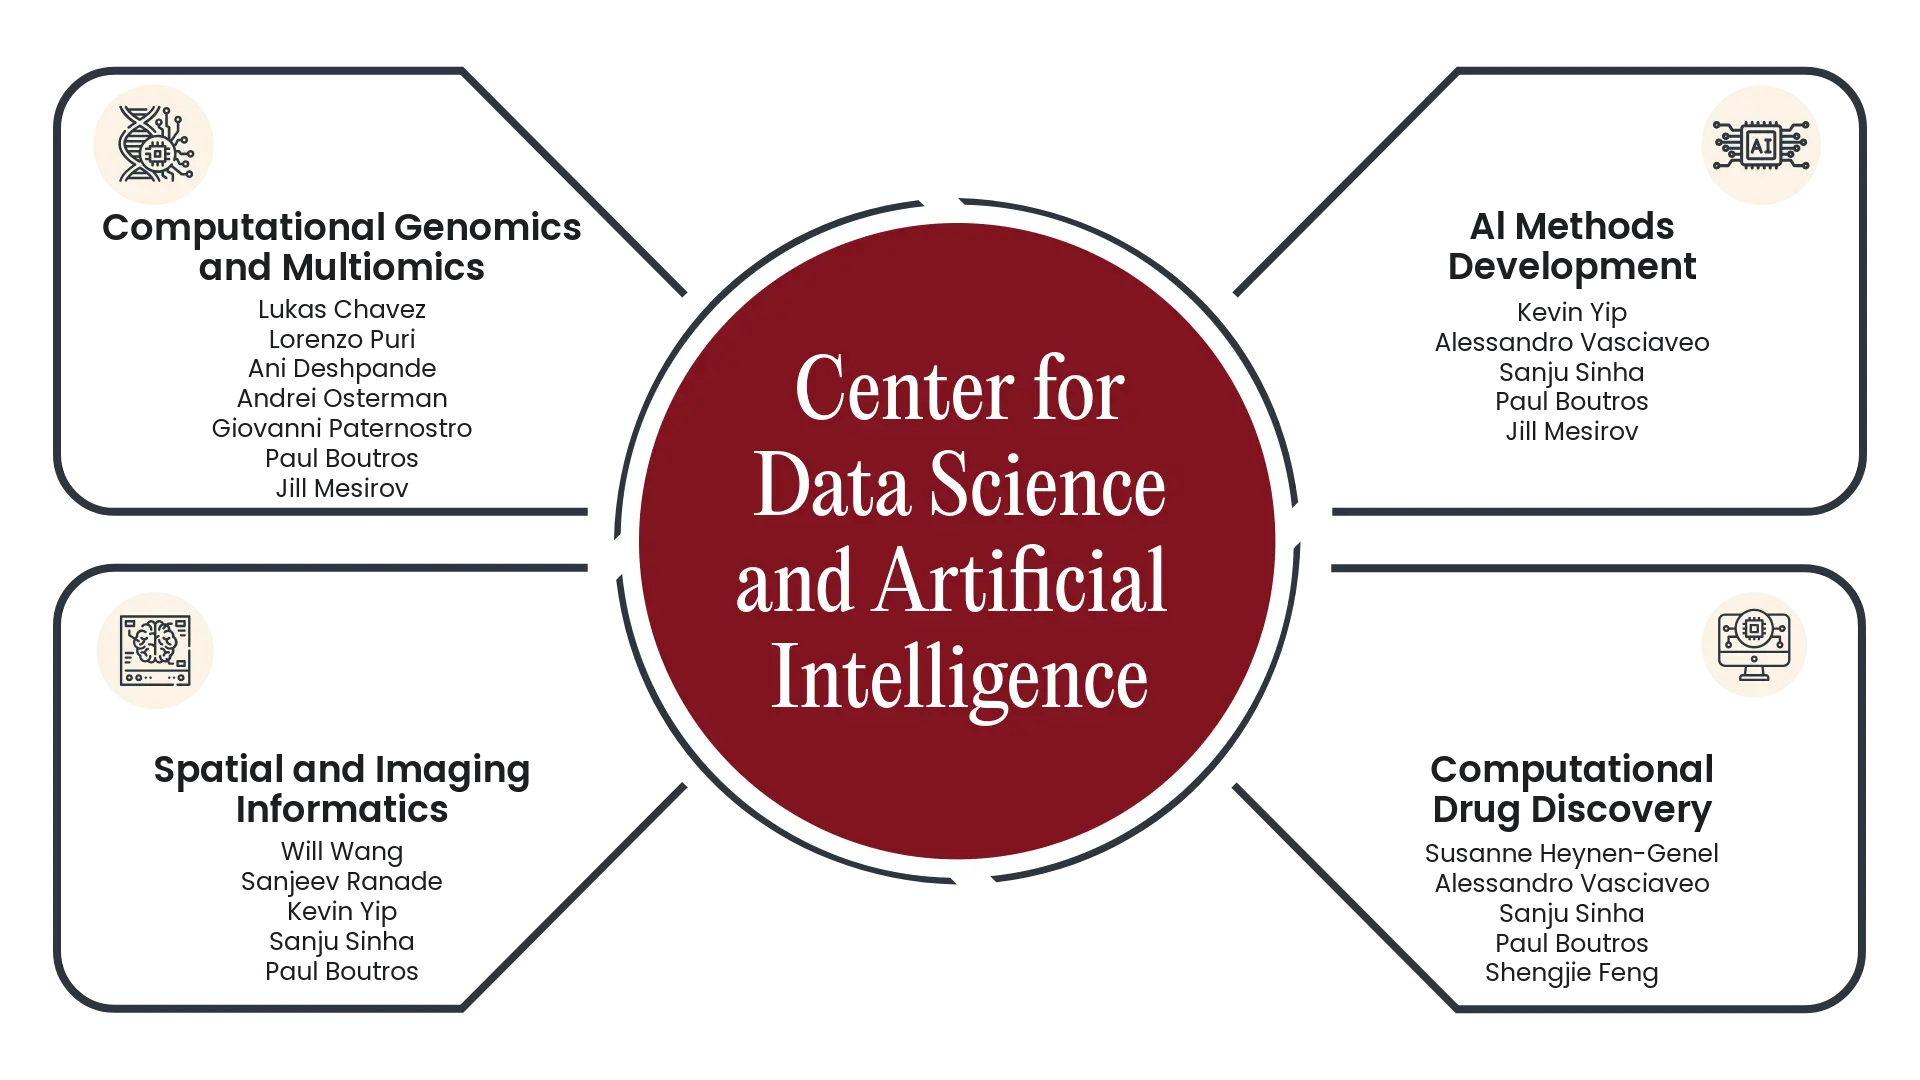
The future of biomedical research depends on our ability to make sense of vast, complex datasets. At Sanford Burnham Prebys, the Center for Data Science and Artificial Intelligence brings together experts in AI, statistics, genetics and more to uncover patterns, generate insights and spark innovation. Their work turns raw information into knowledge that drives scientific breakthroughs and new possibilities for human health.
“To drive groundbreaking discoveries in biomedical research by harnessing the power of data science and artificial intelligence, transforming how we diagnose, treat, and prevent disease.
We achieve this mission by data-centric research, inter-disciplinary collaborations, development and sharing of reusable resources, and contemporary training.”
PERsonalized single-Cell Expression-based Planning for Treatments In ONcology
We build a precision oncology computational approach capitalizes on recently published matched bulk and single-cell (SC) transcriptome profiles of large-scale cell-line drug screens to build treatment response models from patients’ SC tumor transcriptomics. The general objective of this project is to utilize single-cell omics from patients tumor to predict response and resistance. The following figure describe the architecture of PERCEPTION pipeline.
Childhood Cancer Catalog of Circular Extrachromosomal DNA
This portal provides a comprehensive catalog of circular extrachromosomal DNA (ecDNA) associated with childhood cancers, facilitating research and clinical insights. Explore detailed ecDNA profiles, patient information, and access valuable resources to advance scientific understanding and improve patient outcomes.
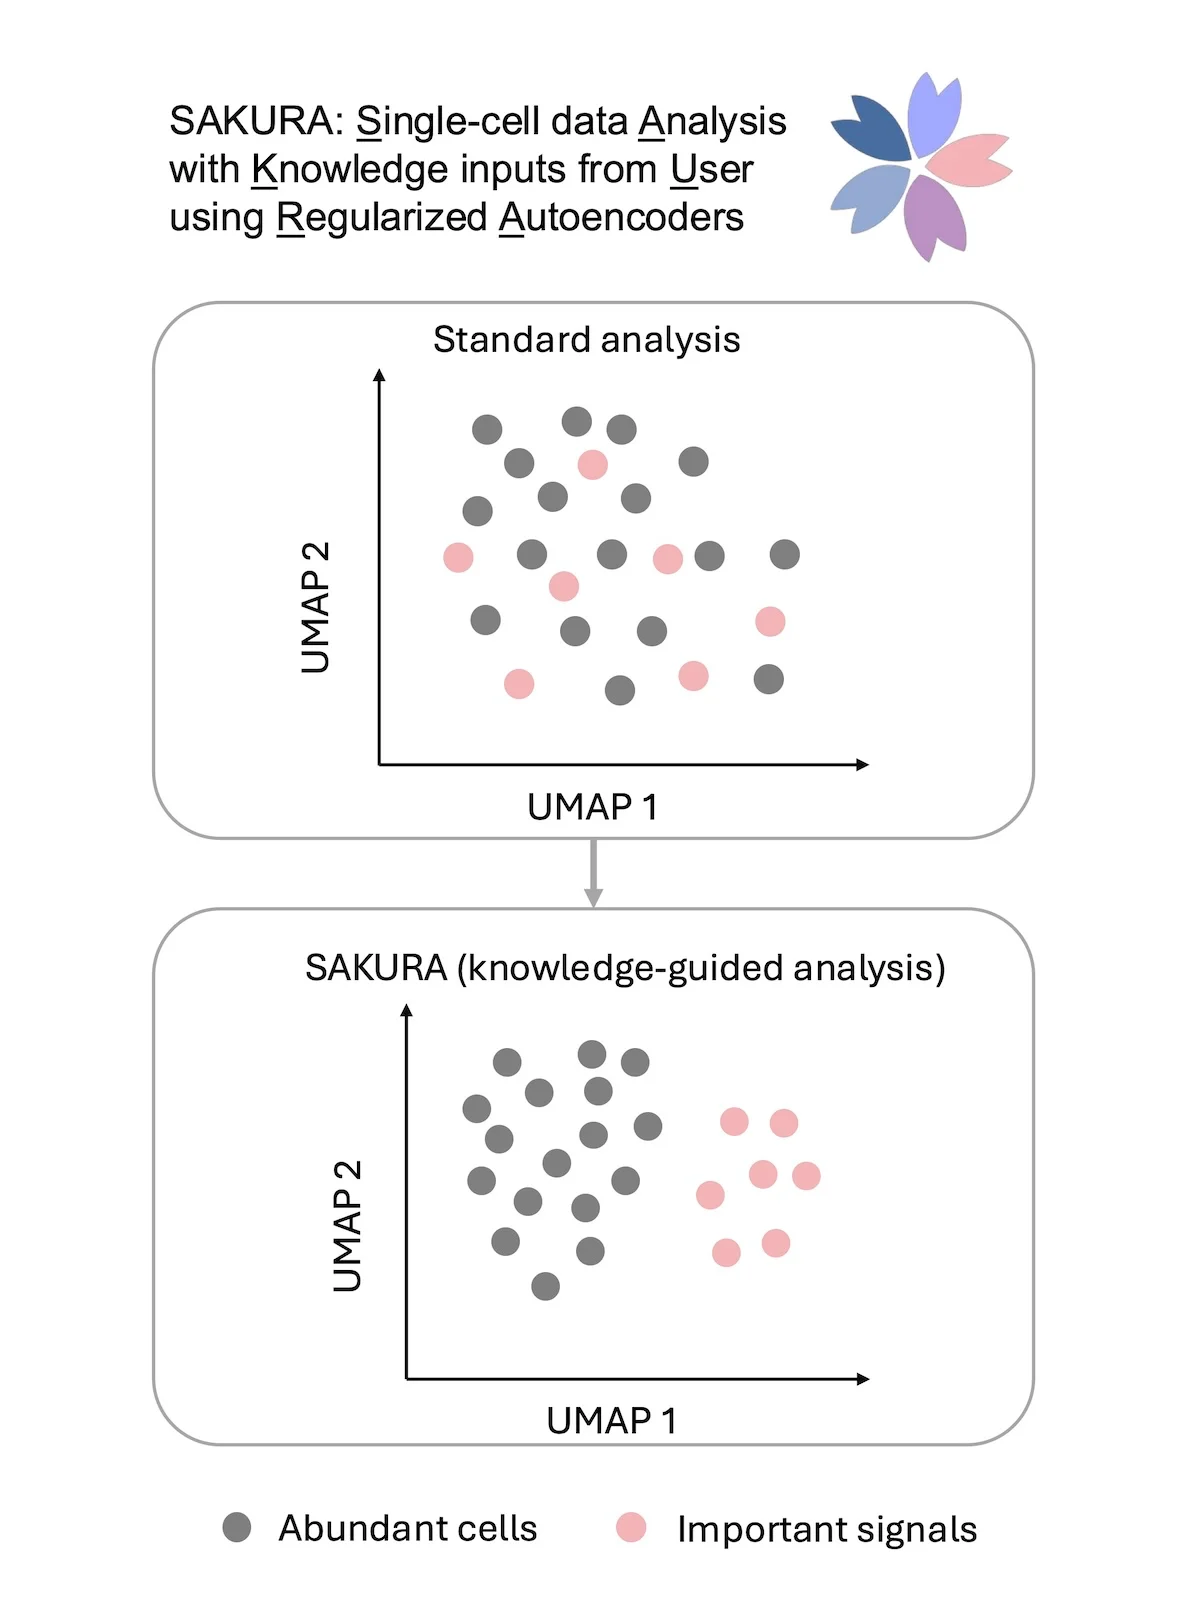
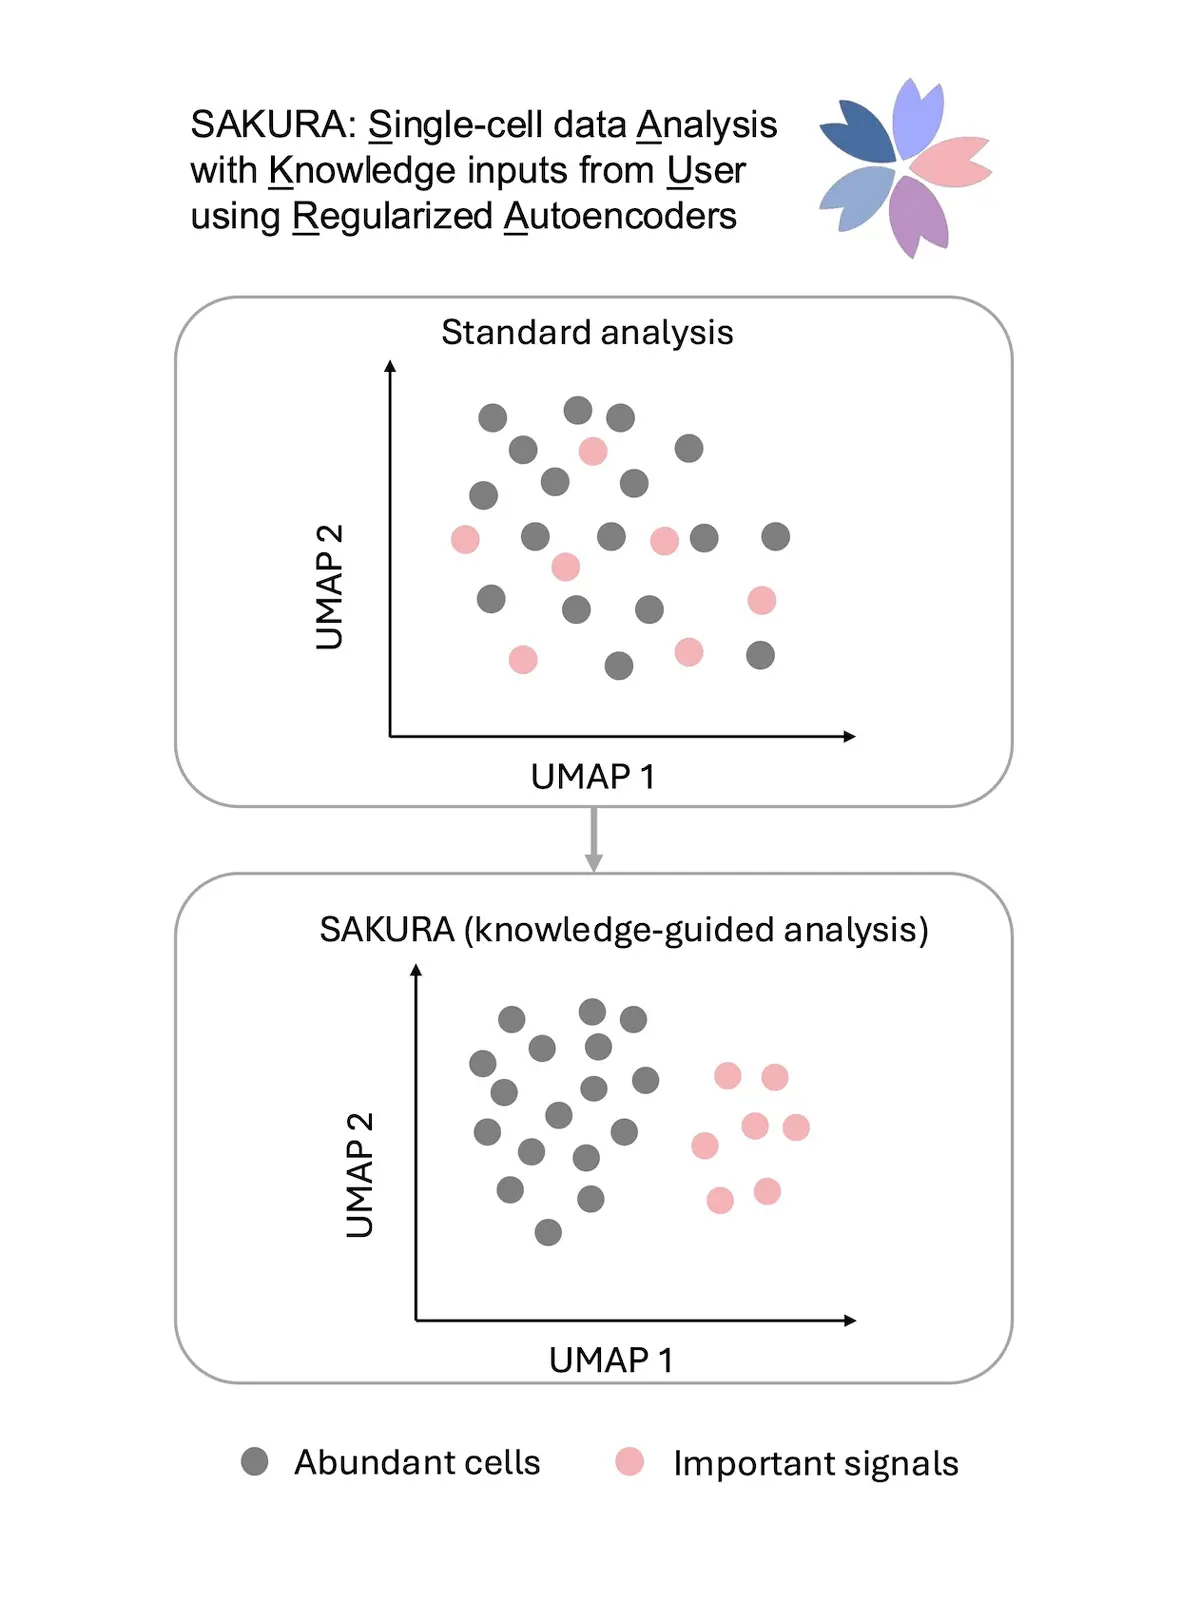
SAKURA: a knowledge-guided approach to recovering important, rare signals from single-cell data
We build a novel framework, SAKURA, that uses knowledge-derived genes of interest to guide dimensionality reduction for scRNA-seq or scATAC-seq data, which can help separate highly similar cell subpopulations and detect rare cells (e.g. senescent cells).
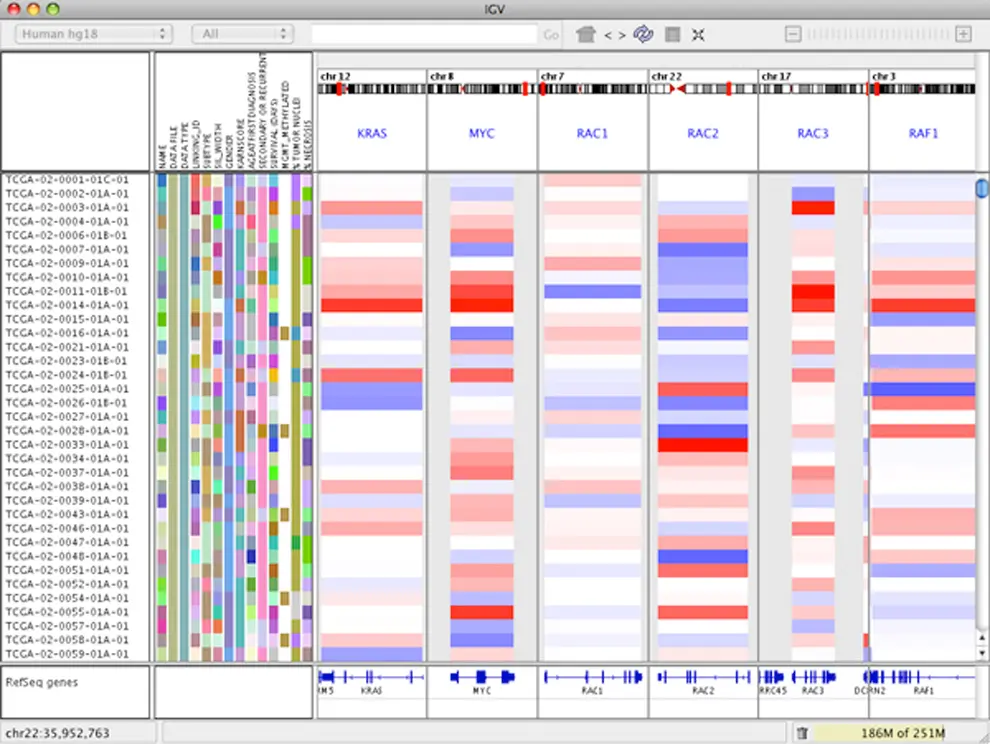
IGV is a high-performance interactive tool for the visual exploration of genomic data. It supports flexible integration of all the common types of genomic data, investigator-generated or publicly available, loaded from local or cloud sources. IGV is available as a desktop application, a web application, and as a JavaScript component that developers can embed in their own web applications.
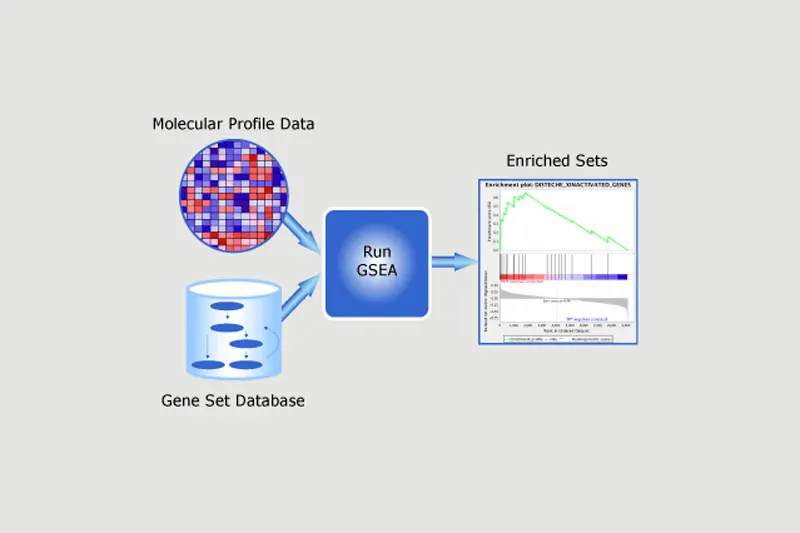
Gene Set Enrichment Analysis (GSEA) and Molecular Signatures Database (MSigDB)
GSEA is a desktop application for gaining insight into the underlying biological mechanisms in gene expression data through the identification of significantly activated or dysregulated biological pathways and processes. GSEA relies on the availability of a priori defined and annotated gene sets, and its companion MSigDB contains over 50,000 curated gene sets in Human and Mouse collections. As an independent resource, MSigDB can also be used with other methods that depend on a knowledgebase of gene sets.
We build a precision oncology computational approach capitalizes on recently published matched bulk and single-cell (SC) transcriptome profiles of large-scale cell-line drug screens to build treatment response models from patients’ SC tumor transcriptomics. The general objective of this project is to utilize single-cell omics from patients tumor to predict response and resistance. The following figure describe the architecture of PERCEPTION pipeline.
This portal provides a comprehensive catalog of circular extrachromosomal DNA (ecDNA) associated with childhood cancers, facilitating research and clinical insights. Explore detailed ecDNA profiles, patient information, and access valuable resources to advance scientific understanding and improve patient outcomes.
We build a novel framework, SAKURA, that uses knowledge-derived genes of interest to guide dimensionality reduction for scRNA-seq or scATAC-seq data, which can help separate highly similar cell subpopulations and detect rare cells (e.g. senescent cells).
PERsonalized single-Cell Expression-based Planning for Treatments In ONcology
We build a precision oncology computational approach capitalizes on recently published matched bulk and single-cell (SC) transcriptome profiles of large-scale cell-line drug screens to build treatment response models from patients’ SC tumor transcriptomics. The general objective of this project is to utilize single-cell omics from patients tumor to predict response and resistance. The following figure describe the architecture of PERCEPTION pipeline.
Childhood Cancer Catalog of Circular Extrachromosomal DNA
This portal provides a comprehensive catalog of circular extrachromosomal DNA (ecDNA) associated with childhood cancers, facilitating research and clinical insights. Explore detailed ecDNA profiles, patient information, and access valuable resources to advance scientific understanding and improve patient outcomes.
SAKURA: a knowledge-guided approach to recovering important, rare signals from single-cell data
We build a novel framework, SAKURA, that uses knowledge-derived genes of interest to guide dimensionality reduction for scRNA-seq or scATAC-seq data, which can help separate highly similar cell subpopulations and detect rare cells (e.g. senescent cells).
Sanford Burnham Prebys scientists say that understanding the potential pitfalls of using artificial intelligence and computational biology techniques in biomedical…
 Sep 14, 2026
 Sep 1, 2026
 Aug 31, 2026
 Aug 19, 2026
 Aug 7, 2026
 Jul 29, 2026